Otto Pro
32GB
512GB SSD
Make local part of your everyday.
A starting point for smaller local models, personal workflows, and cloud support when you need it.
8B–30B quantized local models.
Otto Pro
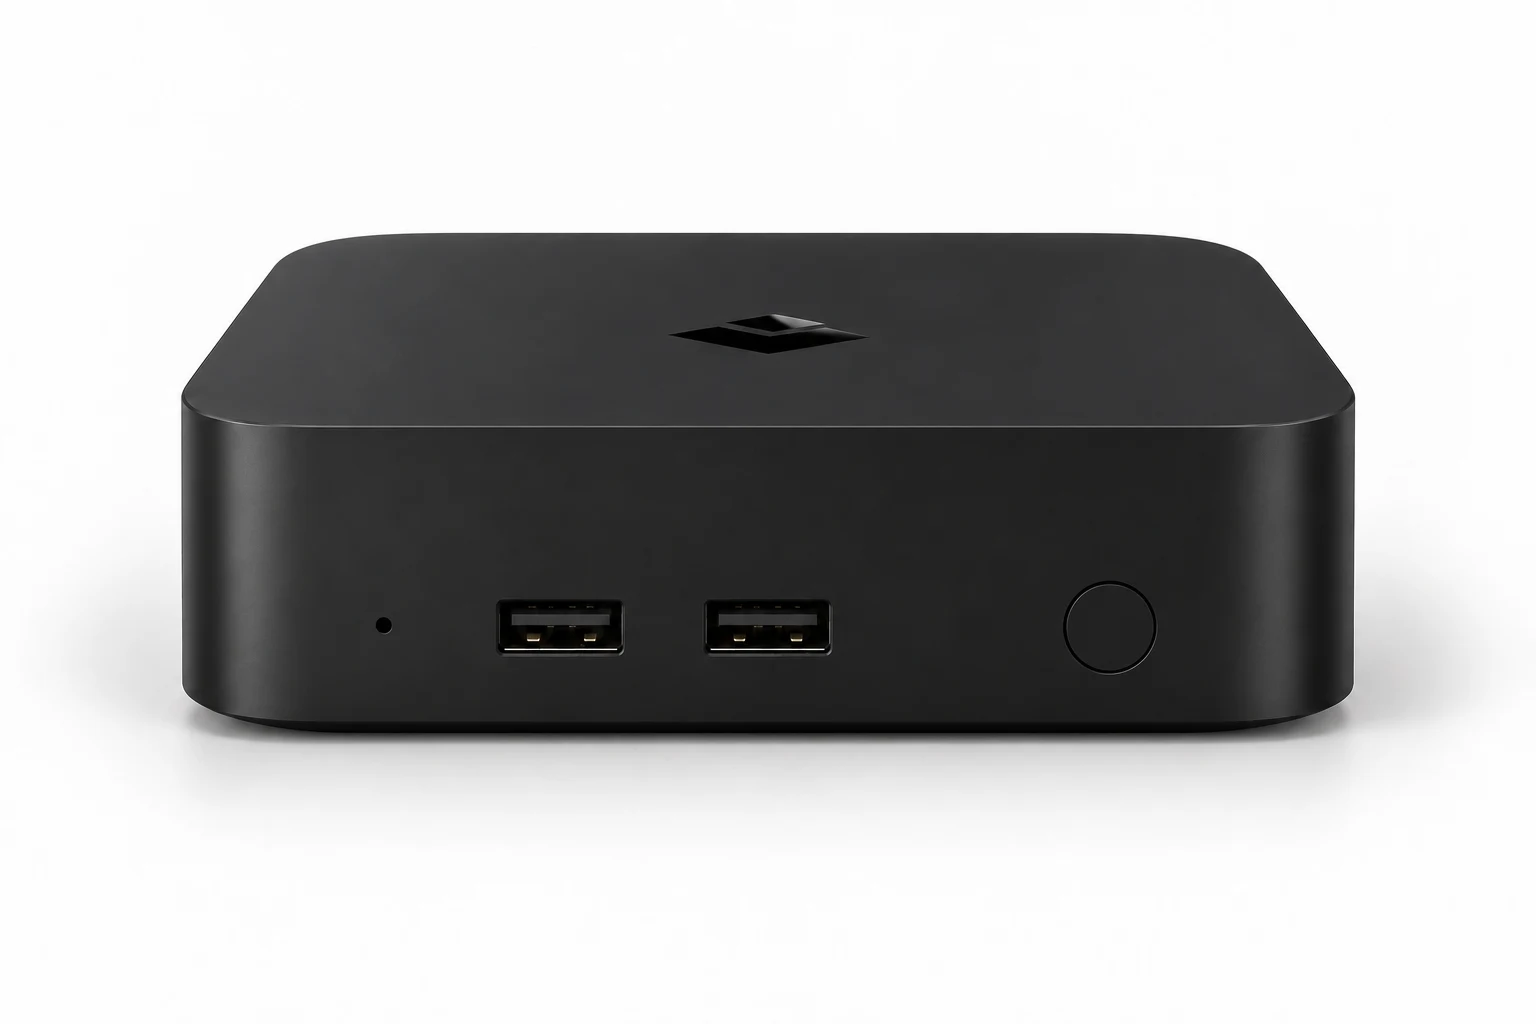
Plug it in. Tap to pair. Put your agents to work.
Dedicated local compute, without the setup headache.
Launching soon — be first to hear.
Ready for local
Spend your time on what your agents can do. Otto brings the local setup together for you.
Install Ollama and assemble your local model setup.
Local compute, built into your Otto experience.
Keep your desktop awake and share its RAM with your day job.
A dedicated machine that stays on for your agents.
Configure endpoints and connect your other devices.
Your agents, accessible through the Otto apps.
Wire up local nodes and cloud providers yourself.
Local and cloud routing, brought together in one place.
Dedicated compute. Your desktop is free to be your desktop.
Connect your Pro to the Otto app.
Give your agents local compute, with cloud access when they need it.
Explore the lineup
One processor. Three configurations. Choose how much room to give your local models.
Otto Pro
512GB SSD
A starting point for smaller local models, personal workflows, and cloud support when you need it.
Otto Pro
1TB SSD
More memory to explore larger models and leave room for the rest of your agent’s work.
Otto Pro
2TB SSD
The most memory in the lineup, for experimenting with larger models and more demanding local workflows.
Side by side
Every Pro has the same AMD Ryzen AI 7 350. Memory and storage scale with the work you want to keep local.
Swipe to compare all three configurations →
| Capability | Otto Pro 32GB | Otto Pro 64GB | Otto Pro 96GB |
|---|---|---|---|
| Local models | 8B–30B quantized | 30B–70B quantized | 70B+ quantized |
| Everyday automation | Good | Very good | Very good |
| Complex reasoning | Limited | Better | Better |
| Multiple agents | Light concurrency | Moderate | More headroom |
| Best for | Individual / prosumer | Power user / SMB | Heavy local AI user |
TOPS are AMD peak specifications, not a measure of local model speed. Bandwidth is the calculated peak across two DDR5-5600 channels; actual throughput varies. Processor specifications
Model size, quantization, and context length all affect memory use and speed. RAM capacity alone is not a performance benchmark.
Local + cloud
Use your Pro for local inference. Reach for cloud models when the task calls for them. Otto brings both into the same agent experience.
Supported models run on hardware you own. Local inference keeps that model’s processing on your device.
Use cloud models for work that needs them. Pay as you go, or connect your own provider keys.
Cloud inference sends the context needed for the task to the selected provider.
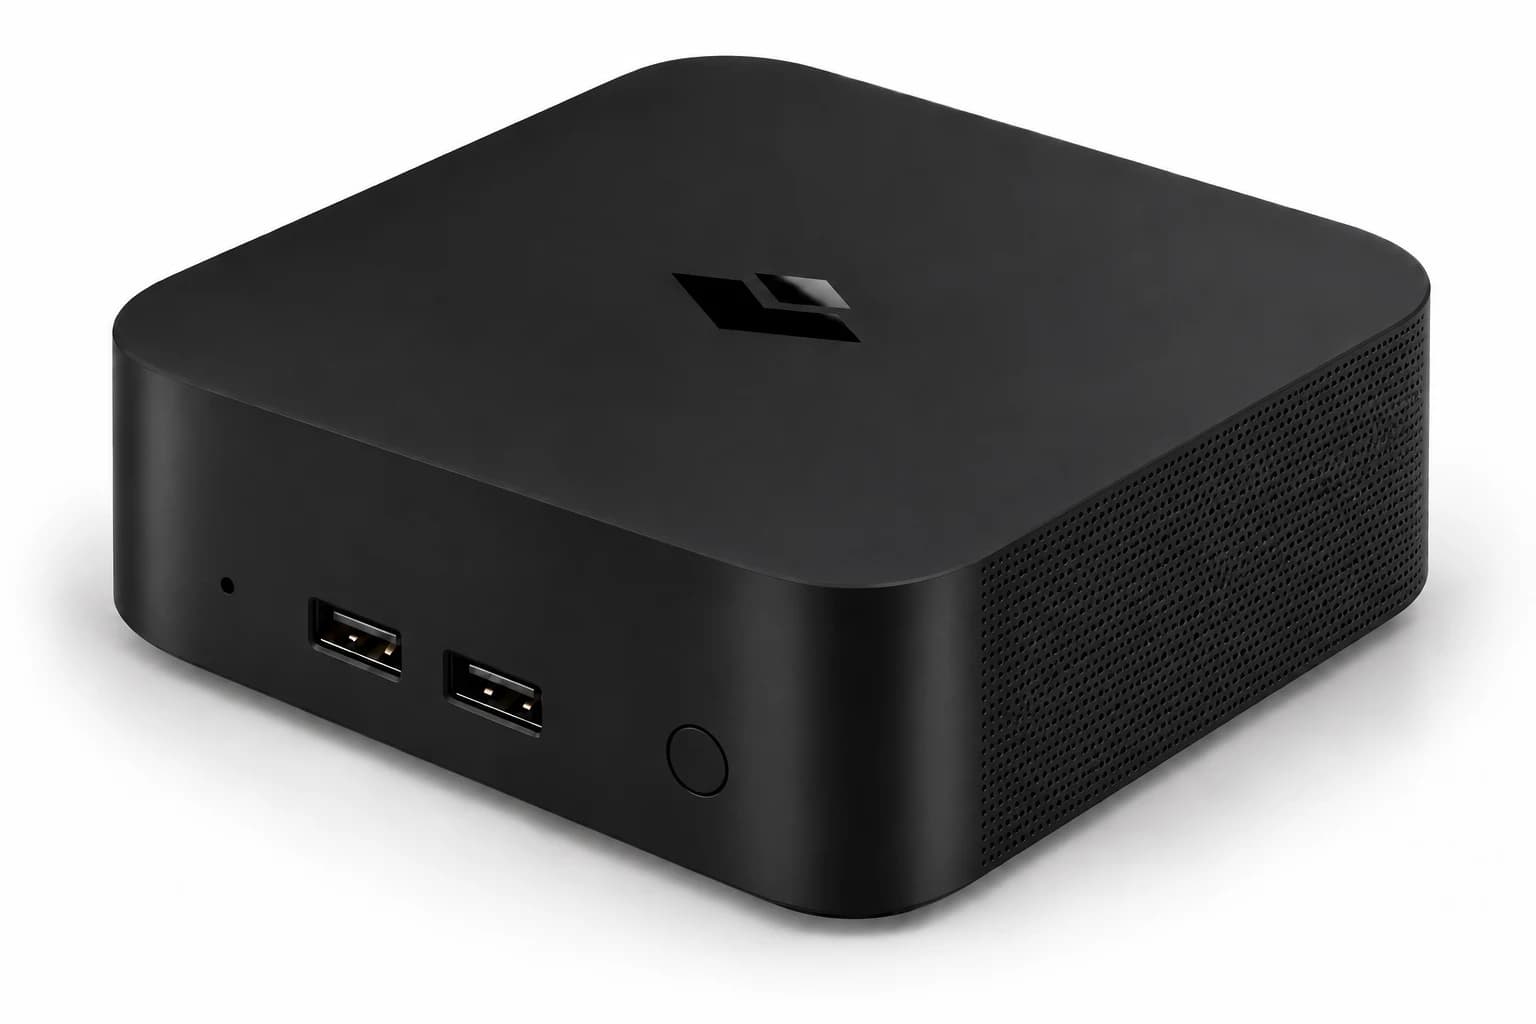
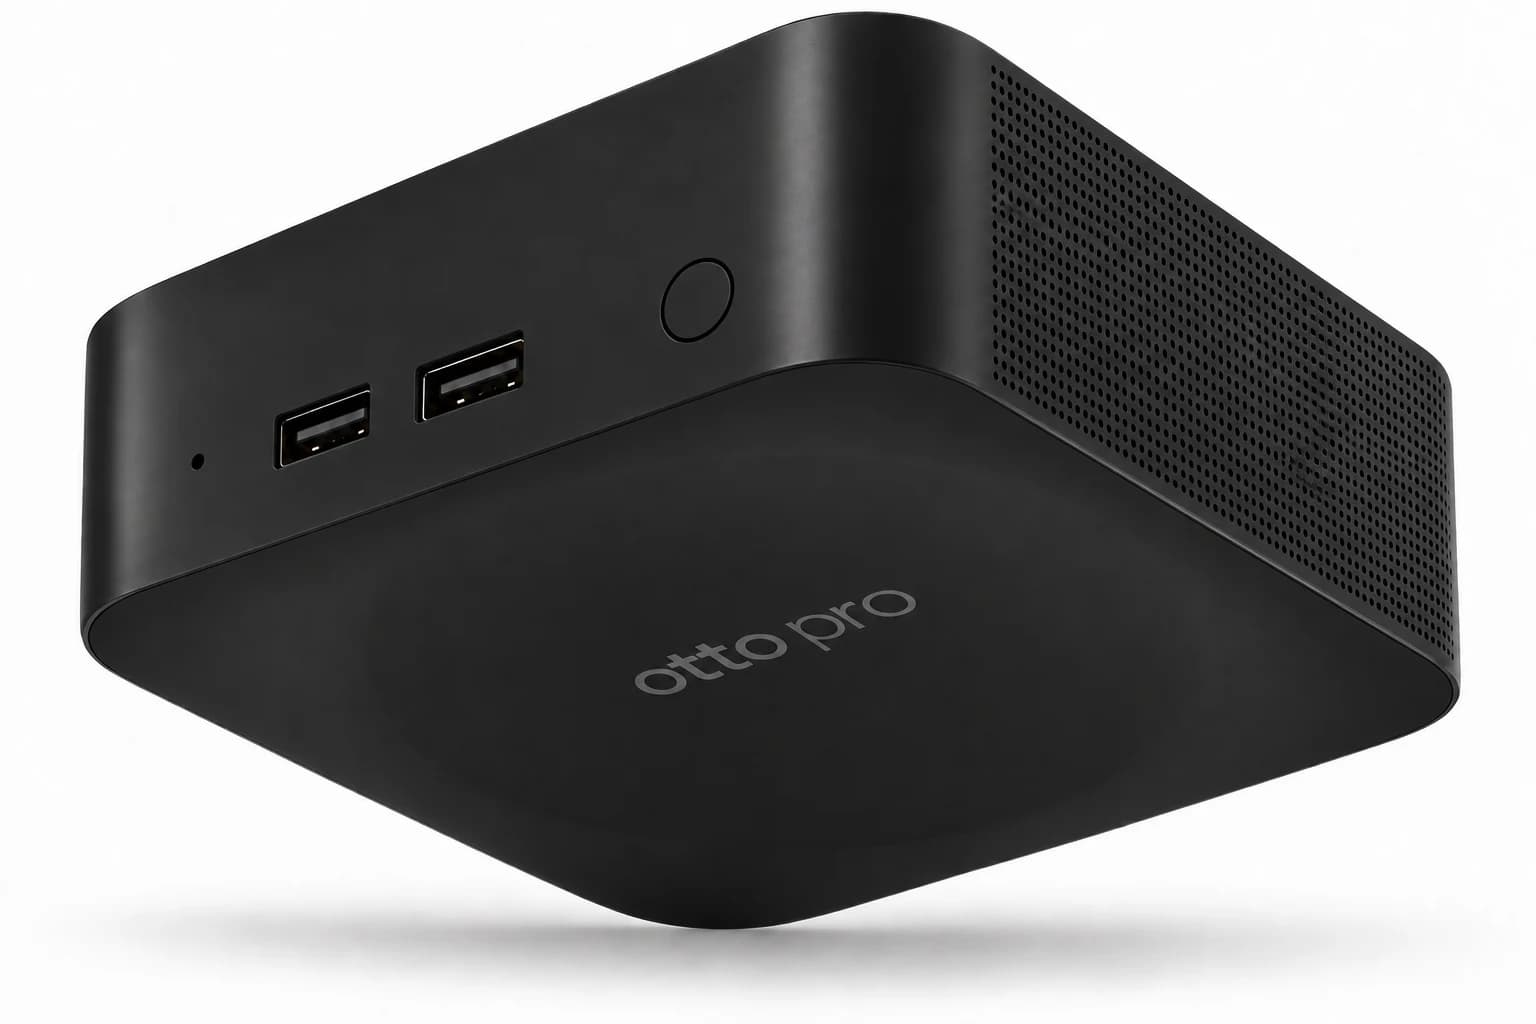
The hardware
Your local models and agent workloads have a machine of their own, without competing for your everyday computer’s memory.
Otto Pro
Be first to hear when Otto Pro launches.
A few things to know
Both give your agents their own computer and the same Otto experience. One is the lower-cost choice for cloud inference. Pro adds more memory and compute for running supported models locally, alongside cloud models when you need them.
Yes. You decide which models your agents use. Choose local models and your agents can run fully on your Pro, with no model usage charges. Frontier cloud models are available when you want them; using them is your choice. The amount and quality of work you can do fully locally depend on your Pro’s compute and the models you choose.
Memory determines how much room you have for model weights, context, and the apps your agents use. All three configurations use the same processor. More RAM gives you capacity for larger workloads; it does not automatically make the same model run faster.
No required Otto subscription. Local inference uses your own hardware. For cloud inference, bring your own API keys or pay as you go through the Otto gateway. Your provider’s usage charges still apply when you use your own keys.
Otto Pro is coming soon. Join the waitlist and we’ll email you when it launches, with pricing and availability. Joining is free and does not reserve a device or require payment.